
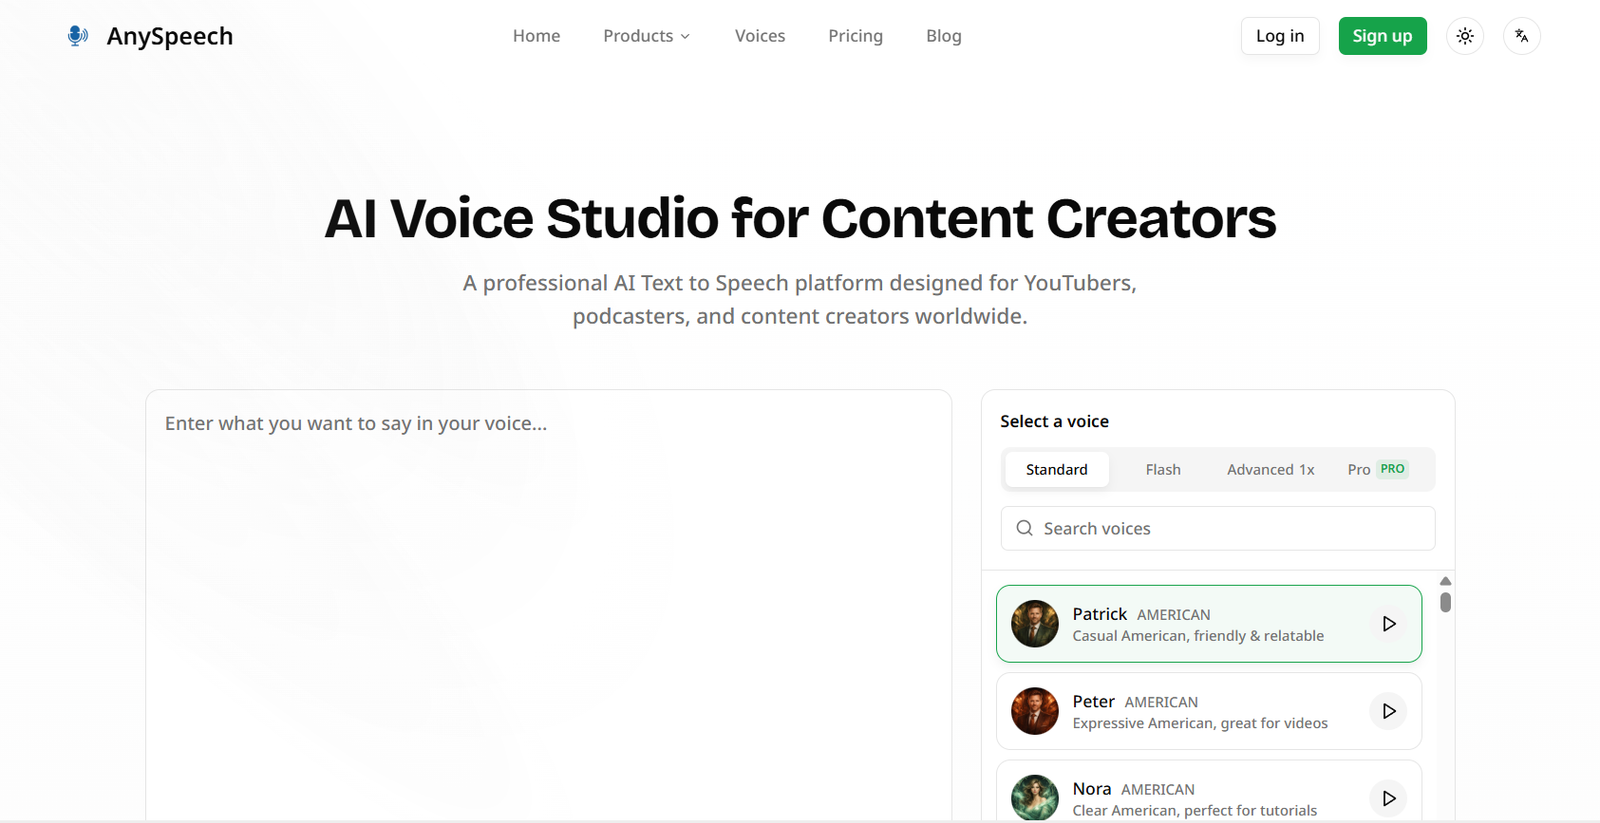
AnySpeech is an AI powered voice platform designed for creators, podcasters, educators, marketers and businesses that need to turn written content into natural sounding speech. Its main AI Voice Studio provides a large collection of voices for creating voiceovers for videos, podcasts, audiobooks, courses, presentations and marketing content.
The platform goes beyond basic text to speech generation. AnySpeech also provides AI voice cloning, speech to text transcription, multilingual voice generation and tools for long form voice projects. Users can adjust aspects of generated speech such as speed, pitch and emphasis to achieve a more suitable delivery.
AnySpeech works through a web browser, making it accessible without installing dedicated audio production software. Its combination of text to speech and speech to text also allows creators to move in both directions, converting written material into audio or recorded speech back into editable text.
Features
AI Text to Speech
AnySpeech converts written text into AI generated speech. Users enter or paste their content, select an available voice and generate audio that can be downloaded for use in different projects.
100+ AI Voices
The platform provides more than 100 AI voices covering different accents, speaking styles and use cases. Available voices include options suited to narration, education, podcasts, business presentations, social media and other content.
50+ Languages
AnySpeech supports text to speech generation in more than 50 languages. Major options include English, Hindi, Spanish, French, German, Italian, Portuguese, Chinese, Japanese, Korean, Arabic, Russian and several additional languages.
Voice Cloning
Users can create an AI version of a voice from a reference recording. AnySpeech offers Lite and Pro voice cloning options. Lite cloning is designed for faster creation, while Pro cloning provides greater fidelity and additional voice controls.
Voice Controls
Generated speech can be adjusted using settings such as speed, pitch and emphasis. This gives users more control over how the AI voice delivers the supplied text.
AI Voice Studio
The Voice Studio is designed for longer content such as YouTube narration, podcasts, audiobooks and online courses. It supports up to 50,000 characters for eligible plans.
Chapter Based Editing
Long form projects can be divided into chapters, helping creators manage large scripts and audiobook style productions more easily.
Multi Voice Narration
Users can work with multiple voices within longer projects. This can be useful for conversations, storytelling, educational content and projects involving several characters or speakers.
Background Music and Audio Mixing
AnySpeech’s long form Voice Studio includes options for working with background music and sound mixing, helping creators prepare more complete audio productions.
Speech to Text
AnySpeech can also convert uploaded audio into written text. Supported upload formats include MP3, WAV, M4A, FLAC, OGG and WebM.
100+ Language Transcription
The speech to text system can automatically detect and transcribe spoken content across more than 100 languages.
Timestamped Transcripts
Transcriptions include timestamps for individual segments. This can make it easier to navigate lengthy recordings or create synchronized captions.
Transcript Translation
AnySpeech can translate generated transcripts into 10 languages, helping users repurpose recordings for multilingual audiences.
Subtitle Export
Transcribed content can be downloaded as SRT or VTT files for use as video subtitles. Standard TXT export is also supported.
MP3 Downloads
Generated AI speech can be downloaded as MP3 audio, making it easy to transfer voiceovers into video editors, podcast software and other applications.
Content Dashboard
Users can save and manage generated speech files through their AnySpeech dashboard and return to previous generations when needed.
How It Works
First, users visit AnySpeech and create an account or begin with the available free options.
For text to speech, users enter or paste the script they want to convert into audio.
They then browse the available AI voices and select one that matches the language, accent and style required for the project.
Voice settings such as speed, pitch and emphasis can be adjusted where available.
AnySpeech processes the text and generates the spoken audio.
Users can preview the result and regenerate or adjust the content if necessary.
Once satisfied, the generated speech can be downloaded as an MP3 file and used in videos, podcasts, presentations, courses or other projects.
For speech to text, users upload a supported audio file. AnySpeech automatically detects the spoken language and creates a timestamped transcript.
The resulting transcription can then be downloaded as TXT, SRT or VTT, or translated into supported languages.
Users interested in creating a personalized AI voice can provide a voice sample and use the voice cloning feature to generate future speech in that voice.
Use Cases
YouTube Creators: Creators can turn video scripts into voiceovers without manually recording every narration.
Podcasters: Podcasters can generate introductions, narration and other spoken segments or transcribe existing episodes into text.
Audiobook Creators: Authors and publishers can create AI narration for books and manage longer projects chapter by chapter.
Educators: Teachers and course creators can convert educational material into narrated lessons and e-learning content.
Marketers: Marketing teams can create voiceovers for advertisements, product demonstrations, promotional videos and social media campaigns.
Social Media Creators: Written scripts can be transformed into audio for Shorts, Reels and other short form content.
Businesses: Companies can create narration for presentations, training materials, product information and internal communications.
Video Editors: Editors can generate voice tracks for videos without arranging separate recording sessions.
Students: Students can turn written study materials into audio for listening and revision.
Accessibility Projects: Text can be converted into speech, while audio can be transcribed into written content to improve access to information.
Podcast and Video Transcription: Existing recordings can be converted into transcripts, captions and subtitle files.
Multilingual Content: Creators can use supported languages to produce voice content for audiences in different regions.
Pricing
AnySpeech offers a free plan along with several paid subscription levels.
The Free Plan costs $0 and includes 5,000 one time credits, up to 5,000 characters per request, voice previews and MP3 downloads.
The Basic Plan costs $9.99 per month and includes 50,000 credits per month, Advanced and Pro voice access, up to 50,000 characters per request and commercial use.
The Standard Plan costs $19.90 per month and provides 100,000 monthly credits with the same 50,000 character maximum per request and commercial usage rights.
The Professional Plan costs $49.90 per month and provides 350,000 credits per month.
The Premium Plan costs $99 per month and includes 800,000 monthly credits.
The Max Plan costs $199 per month and provides 2 million credits per month for users with high volume requirements.
Yearly billing is also available, with the official website currently advertising savings compared with monthly billing.
Additional credit packages can be purchased separately. Current packages range from 40,000 credits for $9.99 to 460,000 credits for $99.99. Purchased credits are stated to remain valid for 90 days.
Speech to text also uses credits based on audio duration. AnySpeech currently provides three free speech to text transcriptions per day.
Pricing, credits and plan features can change, so users should confirm current details before subscribing.
Strengths
One of AnySpeech’s main strengths is that it combines text to speech, voice cloning and speech to text within the same platform.
Its large voice collection gives creators flexibility when selecting voices for different types of projects.
Support for more than 50 text to speech languages makes the platform useful for multilingual content creation, while its transcription service supports more than 100 languages.
The 50,000 character limit on paid plans can be useful for longer scripts, educational content and audiobook projects.
Voice controls such as speed, pitch and emphasis provide additional customization compared with basic text to speech generators.
Its support for TXT, SRT and VTT transcription exports also makes AnySpeech useful for subtitle and accessibility workflows.
A free starting option allows users to test the platform before choosing a subscription.
Drawbacks
AnySpeech uses a credit based system, so users producing large volumes of audio need to monitor their credit consumption.
Pro voices consume credits at a higher rate than Advanced voices, which can reduce the amount of content available within a particular plan.
The free text to speech allowance is relatively limited for users who want to create long form content.
AI generated voices may not always reproduce the emotional detail, pronunciation or delivery of a professional human narrator.
Voice cloning quality can depend heavily on the quality of the reference recording provided.
Long audiobooks, highly expressive performances and specialized pronunciation may still require editing and manual quality checks.
Users should also ensure that they have appropriate permission before cloning another person’s voice.
Comparison with Other Platforms
Compared with simple text to speech generators, AnySpeech offers a broader voice workflow by combining AI speech generation, voice cloning, long form production and audio transcription.
Compared with dedicated transcription services, it provides the additional advantage of generating AI speech from the resulting text, making it useful for creators who need both text to speech and speech to text.
Its long form Voice Studio, chapter based workflow and multi voice narration can make it particularly relevant for audiobook creators, podcasters and YouTubers.
Compared with larger professional AI voice platforms, users should consider factors such as voice realism, emotional control, API availability, cloning quality, language coverage and pricing before choosing a service.
AnySpeech may be especially attractive to users who want several voice related capabilities in one browser based platform rather than maintaining separate services for narration and transcription.
Customer Reviews and Testimonials
Customer reviews and testimonials are not clearly available on the official website.
Conclusion
AnySpeech is a versatile AI voice platform for users who need both speech generation and transcription capabilities. It brings together AI text to speech, more than 100 voices, multilingual support, voice cloning, long form narration and speech to text within a single online environment.
The platform can be particularly useful for YouTubers, podcasters, audiobook creators, educators, marketers and businesses that regularly produce narrated content. Its speech to text and subtitle export capabilities also extend its usefulness to transcription and video captioning workflows.
Users can begin with the free plan to evaluate voice quality and ease of use. Those creating content regularly can choose from several credit based subscriptions depending on their production volume. For creators looking for an accessible combination of AI voice generation, voice cloning and transcription, AnySpeech is worth considering.


